The difference between regression and classification with a network is the same as between linear and logistic regression: only the negative log-likelihood changes. For regression it comes from the normal distribution and gives the mean squared error on an output layer without activation. For classification it comes from the categorical distribution and gives the cross-entropy on a softmax output layer, as for the linear classification of MNIST.
Fitting MNIST
A network with one hidden layer of 100 relu neurons and ten outputs, fitted by AdamW on batches of 32 for 20 epochs.
cross_entropy applies the softmax to the ten outputs and returns the mean negative log-likelihood of the labels.
training accuracy 0.998, test accuracy 0.977
The test error is between 2% and 3%, against about 7.5% for the linear classifier. The network has \(100 \cdot 785 + 10 \cdot 101 = 79510\) parameters, ten times as many as the linear classifier.
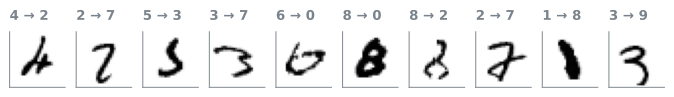
drawing some misclassified test images
with torch.no_grad(): pred = net(X_test).argmax(dim=1).numpy()wrong = np.where(pred != y_test.numpy())[0][:10]fig, axes = plt.subplots(1, 10, figsize=(8.8, 1.3))for ax, i inzip(axes, wrong): ax.imshow(X_test[i].reshape(28, 28), cmap="gray_r") ax.set(xticks=[], yticks=[], title=f"{int(y_test[i])} → {pred[i]}")plt.show()
Figure 34.1: Test images the network gets wrong, with the true label and the prediction.